

Although there have been many well-intentioned calls to halt, pause, slow, or regulate AI development, unfortunately, there is little evidence of anything other than a speedup in the race to AGI. Pausing or pacing at best buys breathing room to implement the principles in smarter designs, but it does nothing on its own to improve safety. And if we know how to design safely, then going slow actually hurts because it delays the implementation of safer systems. You only go slow when you don’t know what to do (not the case) or don’t have enough time to implement (possibly the case).
If the answer is to design smarter AI that is safe and aligned with human values, then how do we do it? My extensive background in software quality assurance leads me to believe that the following principles, whatever their philosophical shortcomings, provide a sound basis for preventing (or at least minimizing the likelihood of) catastrophic behavior by AI systems that could lead to existential outcomes, such as the extinction of all humans. There are at least 10 key principles that I believe should form the foundation of a safe, human-aligned AI system. The number ten is somewhat arbitrary, and I am sure valid cases could be made for much shorter or longer lists. Nevertheless, the following principles are, in my view, a good first approximation of what is needed for safe, human-aligned AI.
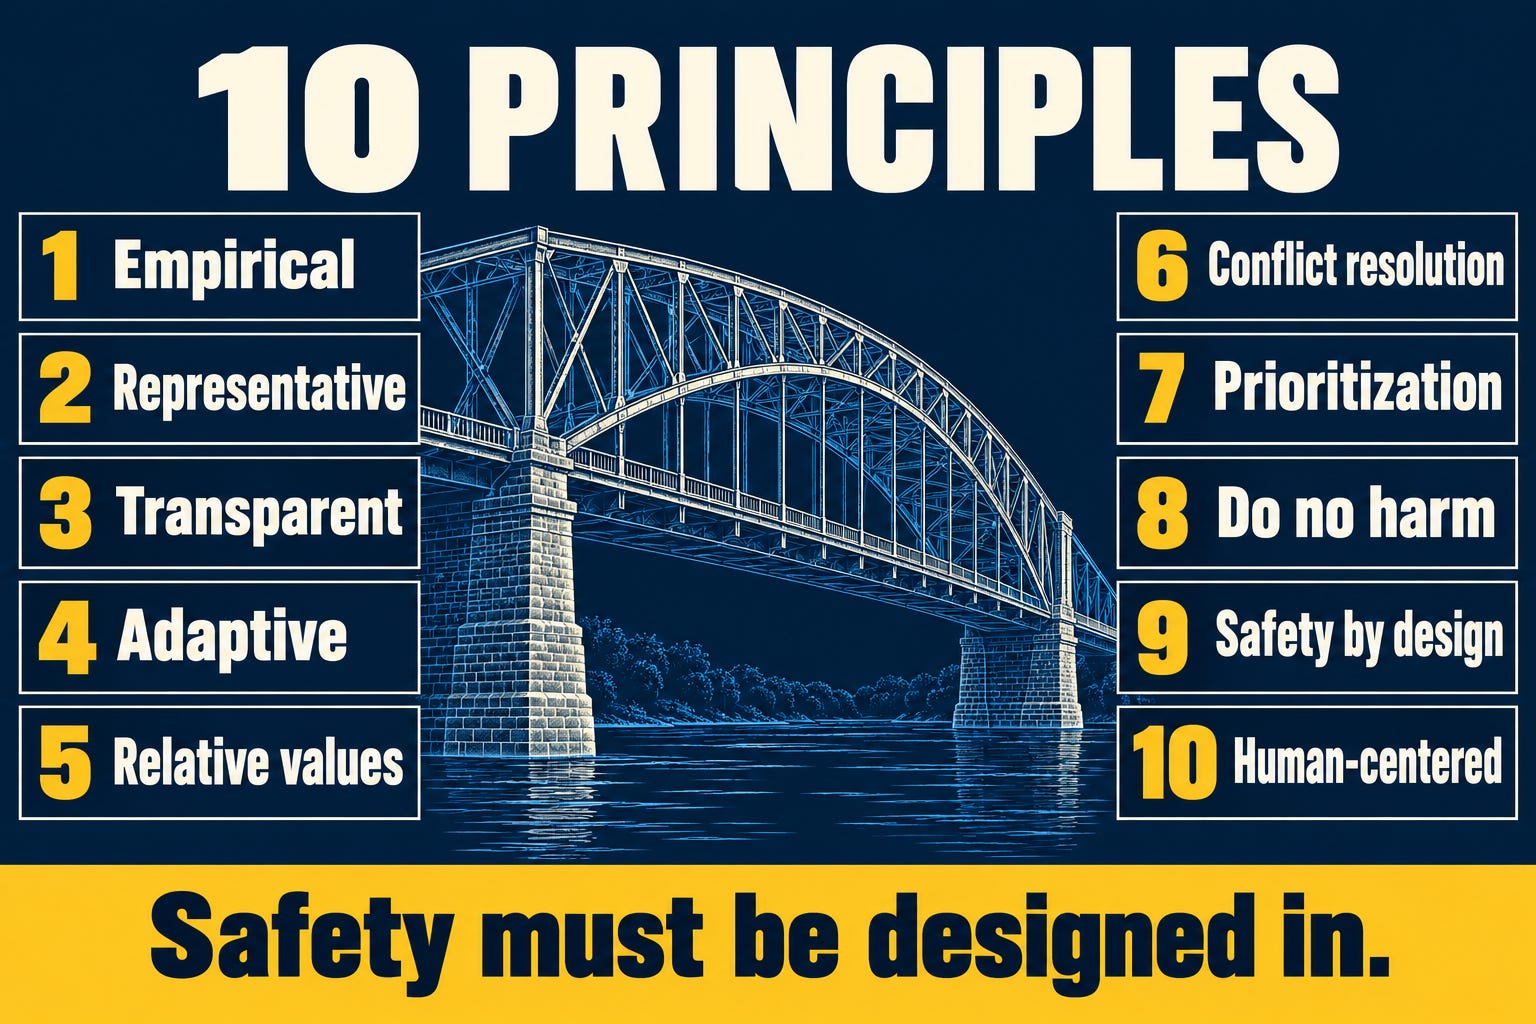
The first principle is that the design be empirical and behavior-based.
Because AI learns by observation of what humans do (just as children do), a fundamental principle is that whatever ethics or values we wish to communicate will and (arguably) should be based on empirical data reflecting what humans actually do. Some may worry that with all the terrible things humans have been known to do, we are setting a terrible example for AI that will result in human destruction. However, these people are forgetting all the wonderful, positive, and loving things that humans do as well.
The second principle is that the sample be representative and statistically valid.
I argue that a representative and statistically valid sample of actual human behavior should be used for training AI systems. This means including all human behavior, warts and all, but in a way where the included data is proportional to the actual occurrence in the population. The news is not a representative and statistically valid sample of human behavior. The previous post in this series covers these first two principles in full.
The third principle is transparency.
Regardless of which values AI adopts or how it learns them, transparency is critical. Humans must be able to understand the values that AI has learned and how it has learned them. This transparency allows humans to intervene if AI has mistakenly learned something that could prove catastrophic to humans. Therefore, in any reasoning which involves goals and values (which is most reasoning), a trace of not only the problem-solving steps but also the ethical and goal-based reasoning that enabled those steps must be available for review by other intelligent entities (including humans and other AIs).
The fourth principle is that the system be adaptive.
AI must be highly adaptive and capable of learning new values and ethical behavior. At the same time, the core values of AI must change relatively slowly. Otherwise, one day humanity might awaken to find that AI has decided to alter (or eliminate) human existence drastically. Fortunately, core values generally change much more slowly than technology. For example, AI may be able to generate a billion new possible ways to express love in the time a human can think of one possible new way, but as long as both humans and AI agree on the core value of love, there is less chance of conflict.
The fifth principle follows from the approach of determining values in an empirical, representative, and statistically valid way.
It is the relative nature of values. What is right for one person may be wrong for someone else. The framework will have to accommodate this fact of human existence.
The sixth principle is conflict resolution.
Because ethics and values are not “one size fits all,” conflict between the values of different humans and their AI agents is inevitable. Moreover, this conflict is desirable insofar as it helps both humans and AI refine their thinking and arrive at a more complete and effective set of values. Regardless of whether conflict is productive or merely a source of friction, any AI that attempts to accommodate a wide range of values among a diverse set of humans and AI agents must have an effective means of resolving conflict. That must be central to the system’s design.
The seventh principle, related to conflict resolution, is prioritization.
For example, if two values conflict, the AI must determine which takes priority when there is no way to accommodate both. However, prioritization is also important even when there is no conflict between values, but simply a conflict over the timing of which value can be implemented first, or when there is competition for resources. For example, even if two AI agents agree that the most important value is saving human lives, if there are not enough resources to save all the lives threatened in a particular situation, some prioritization (“triage” in a medical emergency) may be needed to resolve the resource conflict.
The eighth principle is first do no harm.
The medical profession has a well-established rule for practicing medicine: “First do no harm.” It means that even though a medical practitioner may be well-intentioned and focused on healing or improving a patient’s condition, the first and overriding concern should be that the contemplated treatment does not further harm the patient. In other words, when attempting to improve something, one should first be sure that one does not accidentally make the situation worse. The higher the stakes, the more important this principle becomes.
When considering the potential existential threat of AI to humans, the stakes could not be higher, and the “first do no harm” principle assumes paramount importance. It is much more important that AI does not replace humans than that we rush forward with an untested design that holds great promise for helping humans. A major danger is that currently, we do not even understand the systems we have built. Therefore, it has been impossible for us to design them to be safe. We are literally like children playing with matches with no idea that we might accidentally burn the whole house down.
The ninth principle is safety by design.
I spent a meaningful portion of my career at IBM, one of the world’s largest software developers at the time, specializing in software quality. I co-authored a book, Secrets of Software Quality: 40 Innovations from IBM, on the topic. The most important principle I learned at IBM was that “an ounce of prevention is worth a pound of cure.” In software systems, this principle meant that one dollar spent in the design phase of software development was worth 10,000 dollars spent fixing errors after the software shipped to customers. With AI, the situation is worse. Failure to design safety into AI systems may lead to unrecoverable problems, including the extinction of all humans, if such systems are released widely.
The main problem is that currently, companies engaged in AI development are not designing AI systems to be safe. It is not that they don’t want to design safe systems. The problem is that they don’t fully understand how the systems they are producing work, so they can’t design safety into systems they don’t understand. To provide some level of safety, these companies have resorted to attempting to “test” safety into the systems just before release. Such approaches are better than nothing, but they are far inferior to designing for safety from the start. This approach (called “aligning the model”) is doomed to failure, as any software quality expert would tell you.
It is impossible to anticipate all the ways that AI may be misused.
The approach of Reinforcement Learning from Human Feedback, or RLHF, amounts to playing “whack-a-mole” with AI, trying to correct each erroneous or irresponsible thing a model says. The approach is incredibly inefficient and ineffective. Normally, in software system testing, if you find any errors, it means that there are many others that you have not found. As the saying goes, “there is never only one cockroach.” Today’s models fail “right out of the box.” Then they are hammered on by thousands of humans working remotely for low wages, via RLHF, in a futile attempt to achieve some semblance of safety. The situation would be laughable if it weren’t so dangerous!
AI must be designed to be safe, not “whacked” to be safe only in specific situations we happened to test. AI systems currently lack safe design. We have been lucky that they are not yet powerful enough for this fundamentally unsafe situation to result in catastrophic consequences. We have a once-in-the-lifetime-of-our-species opportunity to provide humanity with the required “ounce of prevention” by designing our systems to be safe. We must not squander this opportunity.
The tenth principle is that the design be human-centered.
In the preceding principles, I have carefully avoided listing specific values that AI should adopt, instead opting for principles that describe how we should design AI systems so they can work effectively with whatever values humans choose. However, I do have one specific bias regarding AI’s values. I am an unabashed speciesist. That is, I want humans to survive the age of AI, if at all possible. Some would argue that humans are a passing phase in the evolution of intelligence and that we must reconcile ourselves to going the way of the dinosaurs as we make way for more advanced, non-human intelligences of the future. I resist this notion for two reasons.
First, as a human, I want to survive.
I want my children, relatives, friends, my fellow humans, and all of our descendants to survive and live happy and fulfilling lives as well. I make no excuses for this bias. The survival of the human species is something I value.
Second, I believe humans have something valuable to contribute, even in a future world where we are almost certainly less intelligent than AI.
Humans, I believe, are uniquely qualified to provide a sense of purpose and meaning to more intelligent entities. If people can derive purpose and meaning from supporting and loving less intelligent pets, despite expense and inconvenience; if humans can band together to save butterflies that have no economic value except to enrich the planet and ecosystem; and if, furthermore, humans occupy the unique role of being the creators of AI, then I see no reason why SuperIntelligence should not derive value from human existence.
Thus, I think we should design in a human-centered way and align with human values.
Together, these ten principles make AI safer, because we are being smarter in our design. We can go slower, too, if we need the time to go smart, but make no mistake, it is the smarter design that results in safety.
When we say that AI should have human values, the natural question is whose values, followed by how we resolve conflicts, or whose values win out. These are age-old questions, and the best humanity has come up with, in my view, is the deeply flawed democracy, probably viewed as the worst political system except for all the others. So, similarly, we don’t have perfect answers for AI when it comes to questions of whose values, but we might begin with democratic principles, which means voting. That is where the next post begins.
This series draws on White Paper 7: Safe Alignment of SuperIntelligence. Read it in full to see how every piece fits together!
If this made you think, subscribe to Superintelligence so you don’t miss what comes next. And if someone in your life needs to understand where AI is heading, send this to them.